Blog
AI Infrastructure.
Practical write-ups, published regularly. New here? Start with the AI Infra roadmap →

Why Kubeflow Trainer Exists: The Journey from Single GPU Training to Distributed AI on Kubernetes
Understand the evolution from single GPU training to PyTorch DDP and discover why Kubernetes needs Kubeflow Trainer to orchestrate distributed AI workloads.
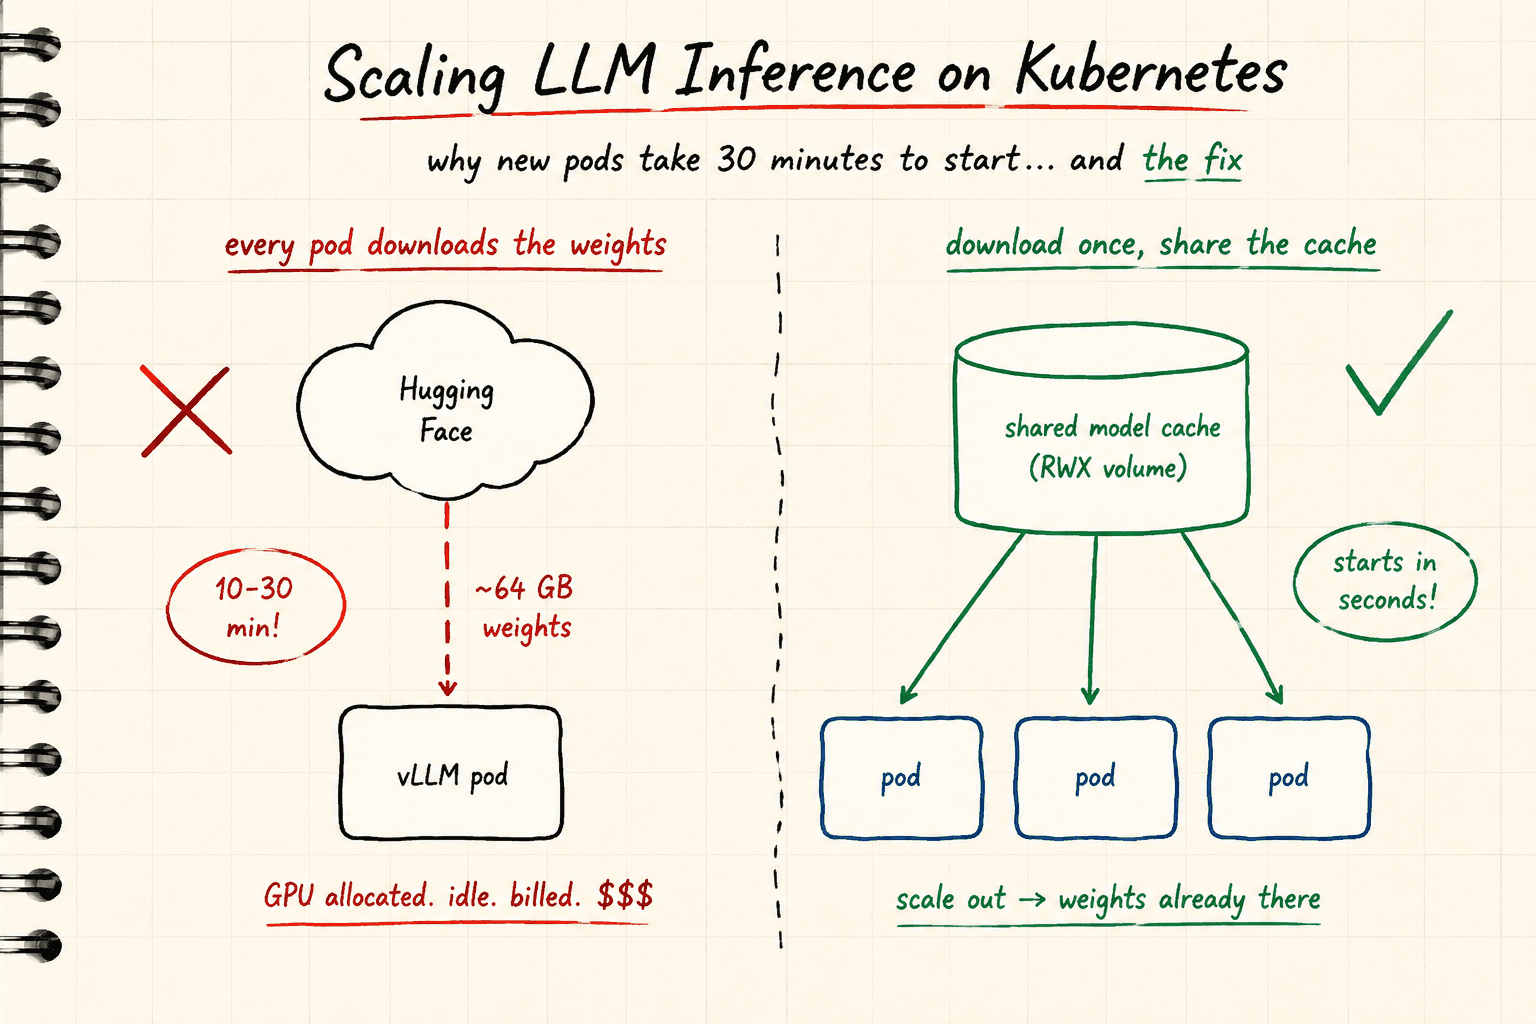
Scaling LLM Inference on Kubernetes: Why Your Pods Take 30 Minutes to Start (And How to Fix It)
Scaling AI models on Kubernetes is not like scaling a normal web service. The reason is simple: large models depend on things Kubernetes was never designed around — tens of gigabytes of model weigh…
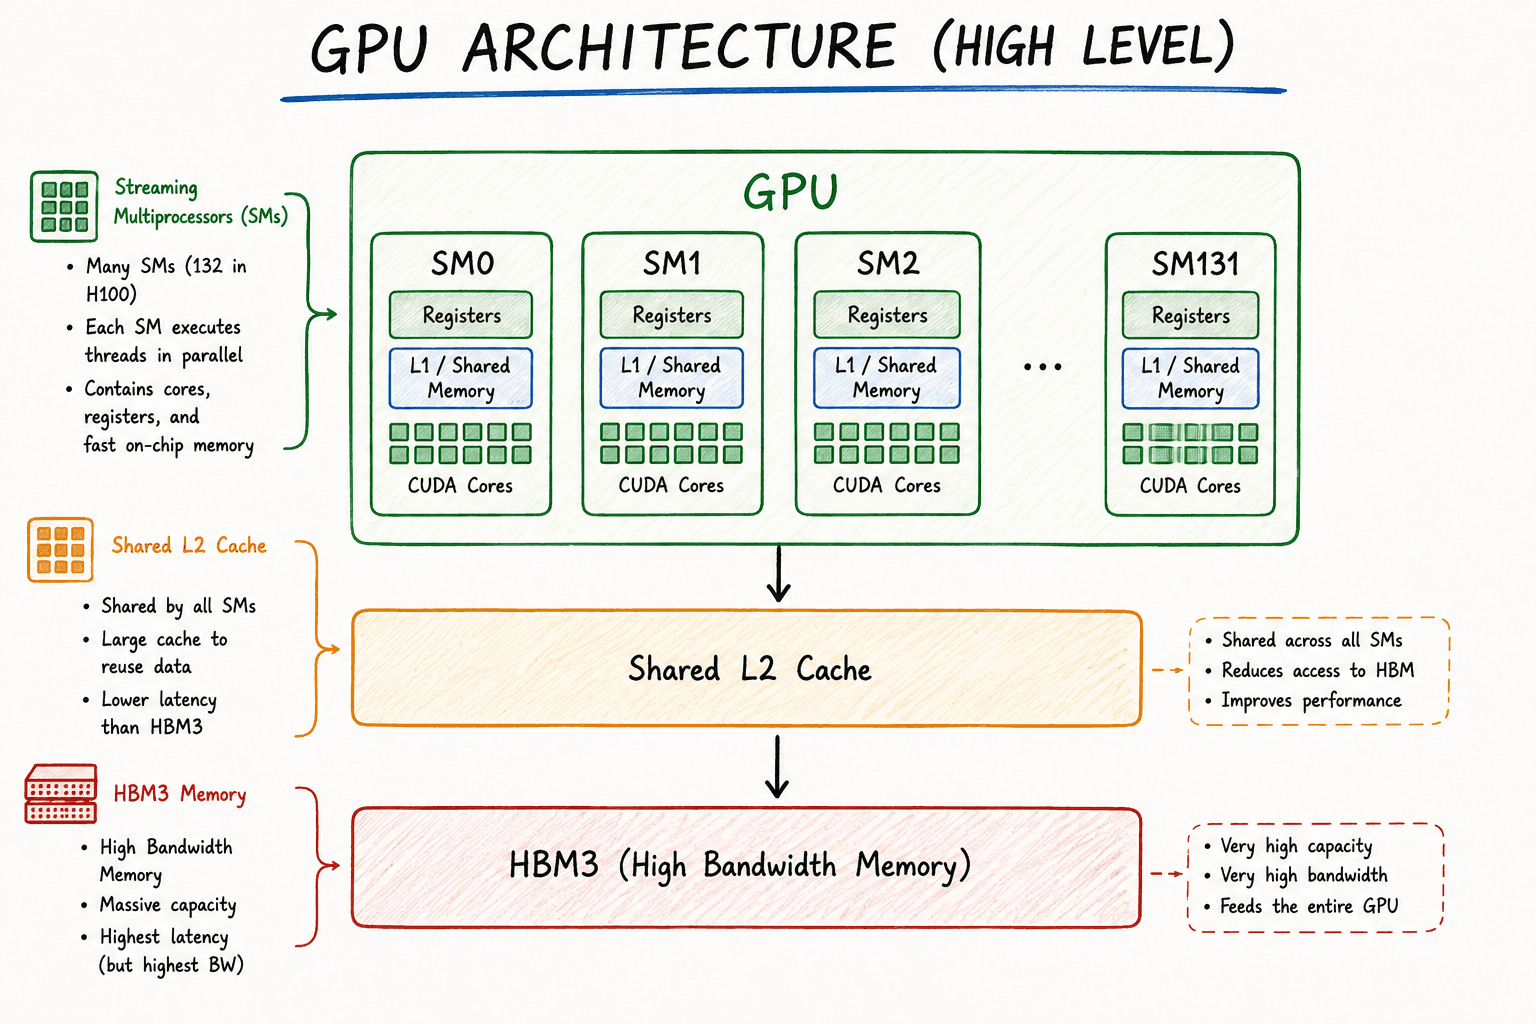
GPU Architecture Explained: How Modern GPUs Execute AI Workloads
A practical guide to modern GPU architecture, explaining how Streaming Multiprocessors, CUDA Cores and Tensor Cores work together to execute AI workloads.
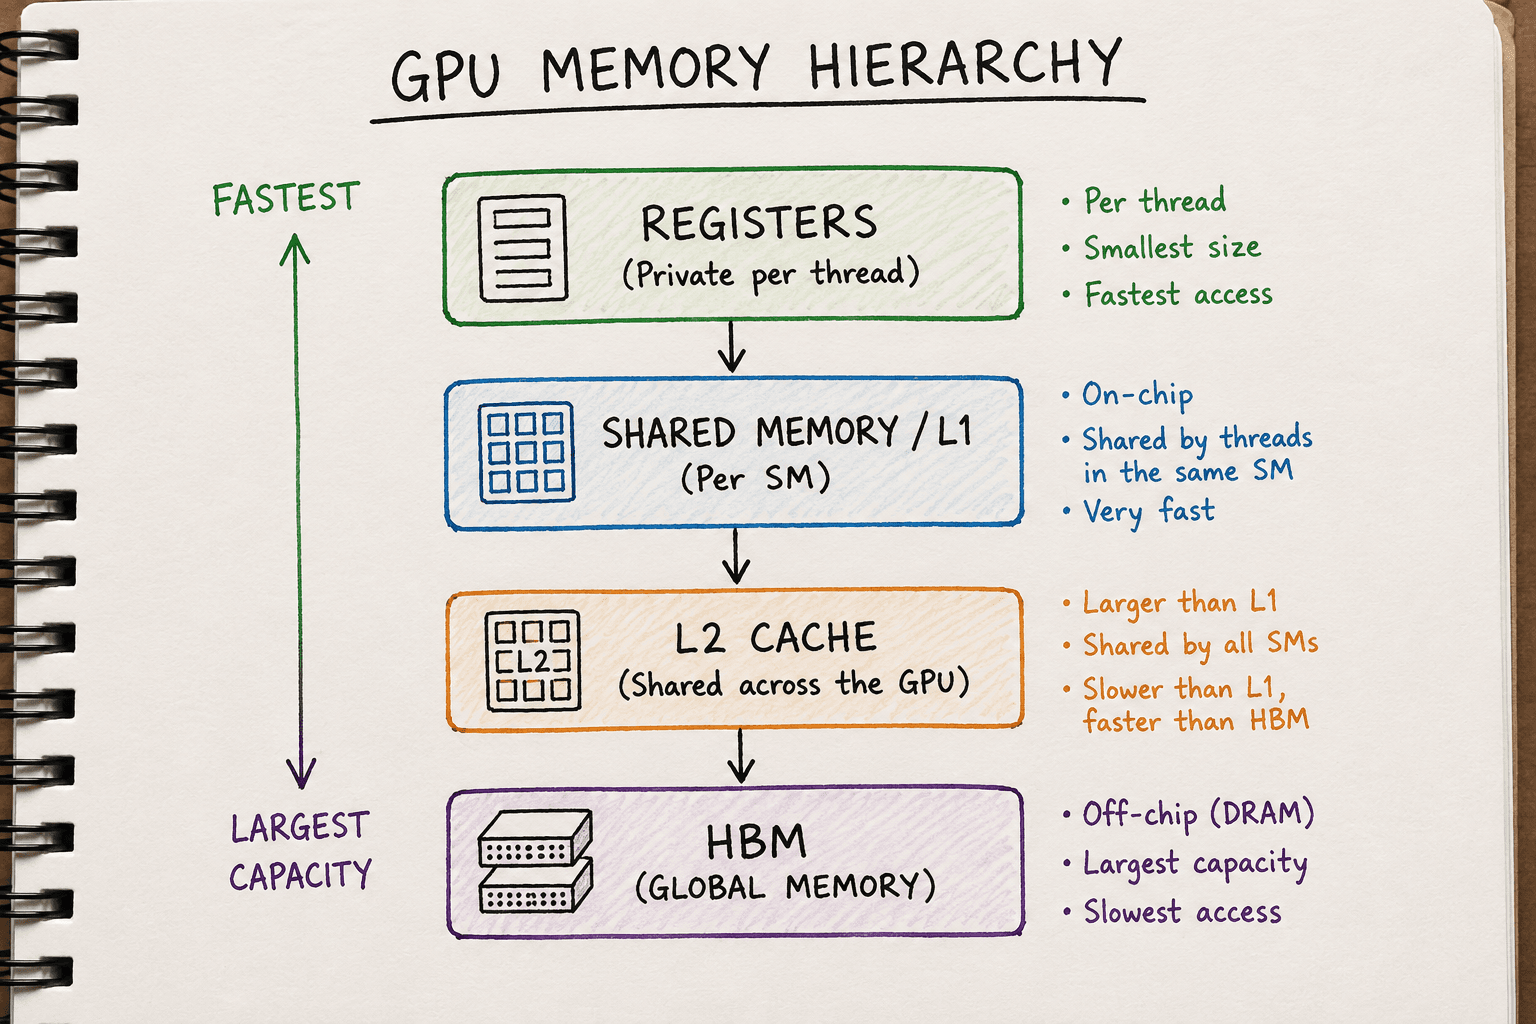
Understanding the GPU Memory Hierarchy
Explore the GPU memory hierarchy, from registers to HBM, and learn how each level of memory impacts GPU performance.
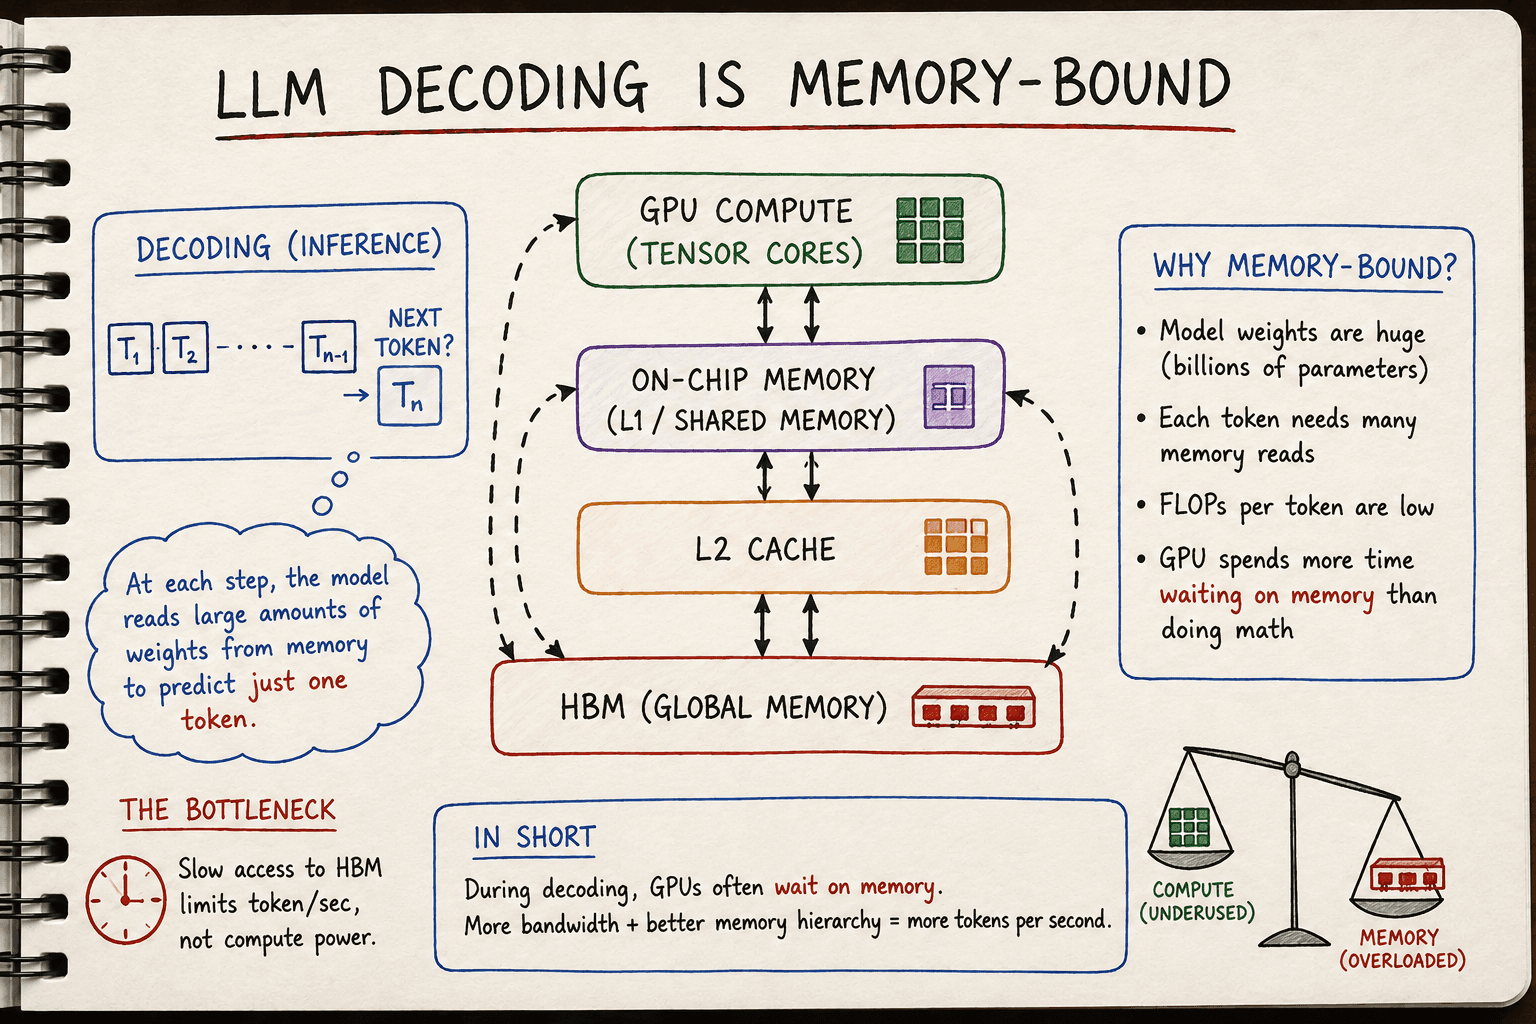
Why Is LLM Decoding Memory-Bound?
Understand why LLM decoding is memory-bound, how memory bandwidth limits token generation, and why Tensor Cores spend most of their time waiting for data.
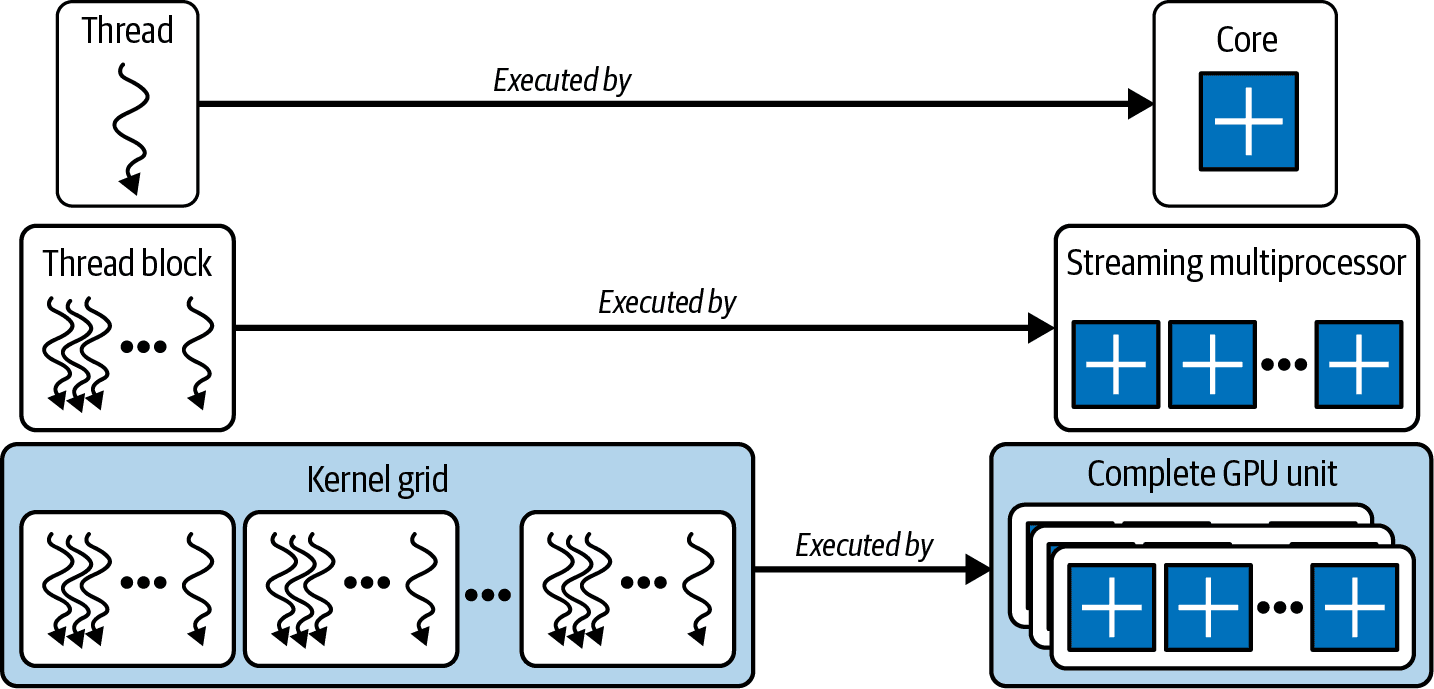
How GPUs Execute Work: Understanding Threads, Warps, Thread Blocks and Grids
A practical explanation of how GPUs organise and execute work using threads, warps, thread blocks and grids.